
Artificial Intelligence
How to Reduce AI Inference Costs Without Killing Quality
How to Reduce AI Inference Costs Without Killing Quality Home
Every AI-powered product eventually hits the same wall: the model works beautifully, users love it, and then the inference bill arrives. What started as a modest experiment turns into a five- or six-figure monthly line item - and the instinctive reaction (swap in a cheaper model, cut context length, throttle usage) often damages the very quality that made the product worth building.
The good news: reducing AI inference costs and preserving output quality are not opposing goals. They simply require a different starting point - treating inference cost management as an engineering discipline, not a last-minute budget fix.
This guide breaks down where inference costs actually come from, the optimization techniques that deliver the biggest savings, and a practical framework for cutting costs without a noticeable drop in quality.
Training gets the headlines, but inference is where the money actually goes once a product ships. Every user query, every API call, and every background job that touches a model adds to a running total that scales directly with usage - exactly the metric every product team is trying to grow.
A few forces are compounding the problem:
Bigger models by default. Teams often reach for the largest, most capable model available "just in case," even when a smaller model would handle most requests just as well. This tendency is especially visible in emerging systems like autonomous agents — we've written before about the cost challenges of autonomous AI systems and why resource-hungry architectures need cost discipline built in from day one.
Unbounded context windows. Longer prompts and retrieval-augmented pipelines quietly inflate token counts on every call.
Redundant computation. Similar queries get processed from scratch repeatedly, with no caching layer in place.
Lack of visibility. Few teams track cost per request, per feature, or per customer - so no one notices the problem until the invoice does.
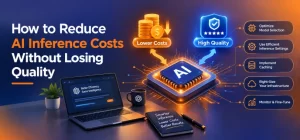
Rather than chasing a single fix, effective AI inference optimization pulls on five levers together. Used in combination, teams typically see a 30–70% reduction in cost with little to no perceptible quality loss.
| Optimization Lever | Typical Savings | Quality Risk if Misapplied |
|---|---|---|
| Model right-sizing | 20–40% | Low, if benchmarked per task |
| Quantization / distillation | 30–60% | Low to moderate on reasoning-heavy tasks |
| Intelligent routing / cascading | 25–50% | Low, with a solid confidence threshold |
| Caching & batching | 15–40% | Moderate if caching is too aggressive |
| Infrastructure & hardware tuning | 10–30% | Low, mostly a cost/latency trade-off |
Not every request needs a frontier model. Classification, short-text summarization, and simple extraction tasks are often handled just as well by smaller, faster, cheaper models.
Benchmark task-by-task, not model-by-model. A smaller model can outperform a larger one on a narrow task once it's fine-tuned or given a well-designed prompt. Beyond model selection, some of the biggest efficiency gains are now coming from next-generation efficient AI architectures designed for lower compute overhead from the ground up.
Model quantization reduces the numerical precision of a model's weights - for example, from 16-bit to 8-bit or 4-bit - shrinking memory footprint and speeding up inference, often with minimal accuracy loss. Distillation goes further: training a smaller "student" model to mimic a larger "teacher" model's behavior on your specific domain.
NVIDIA's own research on post-training quantization for large language models shows that precision reductions can deliver major gains in latency, throughput, and memory efficiency without retraining the underlying model. Independent case studies compiled by infrastructure vendors point to similar outcomes - enterprises combining quantization with smarter preprocessing have reported cutting token consumption by up to 60% while maintaining acceptable output quality.
Instead of sending every request to your most expensive model, build a routing layer:
Simple, high-confidence queries go to a lightweight model.
Ambiguous or high-stakes queries escalate to a larger model.
A confidence threshold or lightweight classifier decides which path a request takes.
This "cascade" pattern is one of the highest-leverage inference cost reduction strategies because it applies the expensive model only where it actually earns its cost.
A significant share of inference traffic in most production systems is repetitive - the same questions, similar prompts, overlapping retrieval results.
Semantic caching stores responses to previously seen (or similar) queries and serves them without a new model call.
Prompt caching avoids reprocessing static parts of a prompt, such as system instructions or long context blocks.
Batching groups multiple requests together for GPU efficiency - especially valuable for non-real-time workloads.
Where and how a model runs matters as much as which model you choose.
Match hardware to workload - smaller models often run efficiently on cheaper GPU instances or even CPUs.
Use autoscaling to avoid paying for idle capacity during low-traffic periods.
Evaluate serverless inference endpoints for spiky, unpredictable workloads versus dedicated instances for steady-state traffic.
Cutting AI infrastructure costs without a plan usually means quality erodes gradually and invisibly - until a customer complains. A structured approach avoids that.
Measure first. Instrument cost per request, per feature, and per model. You cannot optimize what you don't measure.
Set a quality floor. Define acceptable accuracy, latency, and relevance thresholds before touching any cost lever.
Test each lever in isolation. Change one variable at a time - model size, quantization level, cache-hit rate - and measure the quality delta against your floor.
Roll out gradually. Use A/B testing or shadow traffic to validate changes before a full rollout.
Re-benchmark regularly. Model pricing and capabilities change frequently; a routing decision that made sense six months ago may not be optimal today.
The goal isn't the cheapest possible inference - it's the lowest cost that still clears your quality bar. Treat quality as a constraint, not an afterthought.
Switching models wholesale without task-level testing, assuming a cheaper model is "close enough."
Over-aggressive caching that serves stale or generic answers for queries that actually needed fresh context.
Truncating context to save tokens without checking whether the cut information changes the answer.
Ignoring tail cases. Average-case savings can mask serious quality regressions in the edge cases that matter most to users.
Turn on prompt caching if your model provider supports it - often a configuration change, not an engineering project.
Add a confidence-based router between two model tiers you already use.
Audit system prompts and retrieval context for redundant or oversized content.
Set up basic cost-per-request dashboards if you don't already have them.
Getting this right consistently - across models, workloads, and shifting pricing - is exactly the kind of infrastructure work best handled with dedicated expertise. Our AI infrastructure consulting services help engineering teams build cost-aware AI systems that scale without compromising on quality.
Token volume - the combination of input context length and output length - is typically the single largest driver, followed by model size and request volume.
Modern quantization techniques (8-bit and even 4-bit) typically preserve accuracy within a very small margin for most tasks, though reasoning-heavy or highly specialized tasks should be tested carefully before deployment.
Not necessarily. A basic version can start with a simple confidence-score threshold or keyword-based router directing traffic between two model tiers, then grow more sophisticated over time.
It depends heavily on traffic patterns, but production systems with meaningful query overlap often see 20–40% of requests served from cache once semantic caching is implemented well.
Yes - cost problems compound with scale. Building cost-awareness into your architecture early is far cheaper than re-architecting after usage has already grown.
Quarterly, at minimum. Model pricing, capabilities, and available optimization tools change frequently enough that a strategy set once and left alone will drift out of date.
Reduce inference costs without compromising quality. Build a more efficient, scalable AI infrastructure today.
Talk to UsHow to Reduce AI Inference Costs Without Killing Quality Home
Edge Computing & AI for Real-Time Business Intelligence Home Edge
Cybersecurity Mesh Architecture: Why Organizations Are Adopting It Home Cybersecurity
Give us a call or fill in the form below and we’ll contact you. We endeavor to answer all inquiries within 24 hours on business days.