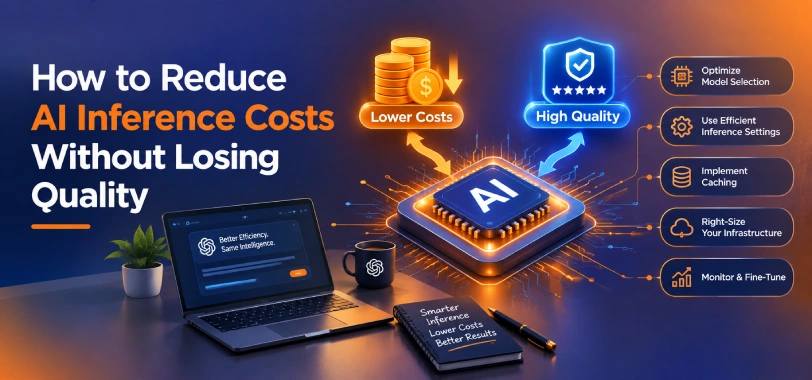
How to Reduce AI Inference Costs Without Killing Quality
How to Reduce AI Inference Costs Without Killing Quality Home AI Cost Optimization Guide How to Reduce AI Inference Costs Without Killing Quality Monthly AI inference spend climbing each month Monthly AI Inference Spend usage ↑ = spend ↑ $6k$9k$13k $17k$22k$27k M1M2M3 M4M5M6 The inference bill arrives Every user query, API call, and background job adds to the total. Inference spend scales directly with usage — exactly the metric every product team is trying to grow. Every AI-powered product eventually hits the same wall: the model works beautifully, users love it, and then the inference bill arrives. What started as a modest experiment turns into a five- or six-figure monthly line item – and the instinctive reaction (swap in a cheaper model, cut context length, throttle usage) often damages the very quality that made the product worth building. The good news: reducing AI inference costs and preserving output quality are